
Introduction
Video Diffusion Models extends image denoising into time, combining image and video training with clip extension. It supplies a research account of temporal continuity behind later video-generation services.
 View full image ↗
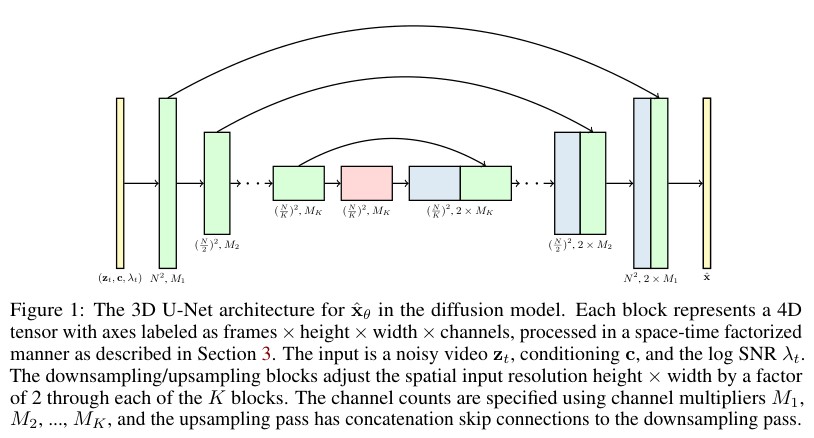
Figure 1: the paper’s space–time-factorised 3D U-Net architecture. Source: v2; the image version is distinct from the initial submission date.
Ho, Jonathan; Salimans, Tim; Gritsenko, Alexey; Chan, William; Norouzi, Mohammad; Fleet, David J. · original paper / arXiv · Rights in the paper and depicted works remain with their holders. Research quotation does not establish an open licence; republication rights await independent review.
Source · Video Diffusion Models ↗RESEARCH ACCOUNT
Video Diffusion Models extends image denoising into time, combining image and video training with clip extension. It supplies a research account of temporal continuity behind later video-generation services.
ANTI-AI ARCHIVE · Revised 2026-10-03
What the paper investigates
The paper extends an image diffusion architecture to video and combines image and video data during training. Conditional sampling supports spatial and temporal extension. Its experiments distinguish text-conditioned generation, prediction and unconditional synthesis, making the learning task visible behind the resulting moving image.
Section sources: Video Diffusion Models
Its place in generative-art history
Editorial interpretation: the historical question is how a sequence takes shape, beyond animating a still image. The paper provides a methodological context for later services and makes duration and temporal continuity explicit conditions of production.
Section sources: Video Diffusion Models
Reading limits and versions
The abstract and selected original pages support this account; experiments were not reproduced, and priority claims are not adopted as art-historical firsts.
Section sources: Video Diffusion Models
Sources for this account
Read the arXiv abstract, authors and version history, plus the selected figure/page on PDF page 3; proofs and full experiments were not independently audited.
Read the arXiv abstract, authors and version history, plus the selected figure/page on PDF page 3; proofs and full experiments were not independently audited. The account and translation are AI-assisted, pending independent human review. Section references identify evidence without claiming independent verification of every historical statement.
Continue with a comparative question
Video Diffusion Models: compare methods, control or evaluation conditions with Make-A-Video.
Video Diffusion Models: compare methods, control or evaluation conditions with Stable Video Diffusion.
Dates & version record
Date displayed for this node: 2022-04-07 · Historical date recorded for the source: 2022-04-07
The timeline uses the initial arXiv submission, distinct from conference publication, model release and the archive addition on 3 October 2026. The account and image refer to v2; its date is recorded in the source history.
These dates refer to the historical event or recorded version, not this page’s publication date. The original date precision and unresolved questions are retained.
Original sources & further reading
These links lead to the cited paper, article, institution or conference page. External texts retain their source languages.
Read the arXiv abstract, authors and version history, plus the selected figure/page on PDF page 3; proofs and full experiments were not independently audited.
Provenance, translation & verification
Archive node #172 · Initial research-paper submission; methods, evaluation and production conditions
Research materials & supplement references · 1
Recent research papers: additions and reconciled sources since 2022 · Read the arXiv abstract, authors and version history, plus the selected figure/page on PDF page 3; proofs and full experiments were not independently audited. · 001
Date as recorded: 2022-04-07
Video Diffusion Models ↗
Video Diffusion Models
Archive account based on the listed research materials, not a full translation of the linked work. AI-assisted translation; independent human review pending.
Official material was read within the stated scope; see the source note for reading limits and outstanding checks.
Cite this node
ANTI-AI ARCHIVE. Video Diffusion Models. Art-history node #172. https://salondesrefuses.cn/en/art-history/324
For specific historical claims, also cite the original sources above and include your access date. This account is not a full translation of the linked work.
Adjacent nodes follow chronological order; adjacency does not establish direct influence or causation.