
Introduction
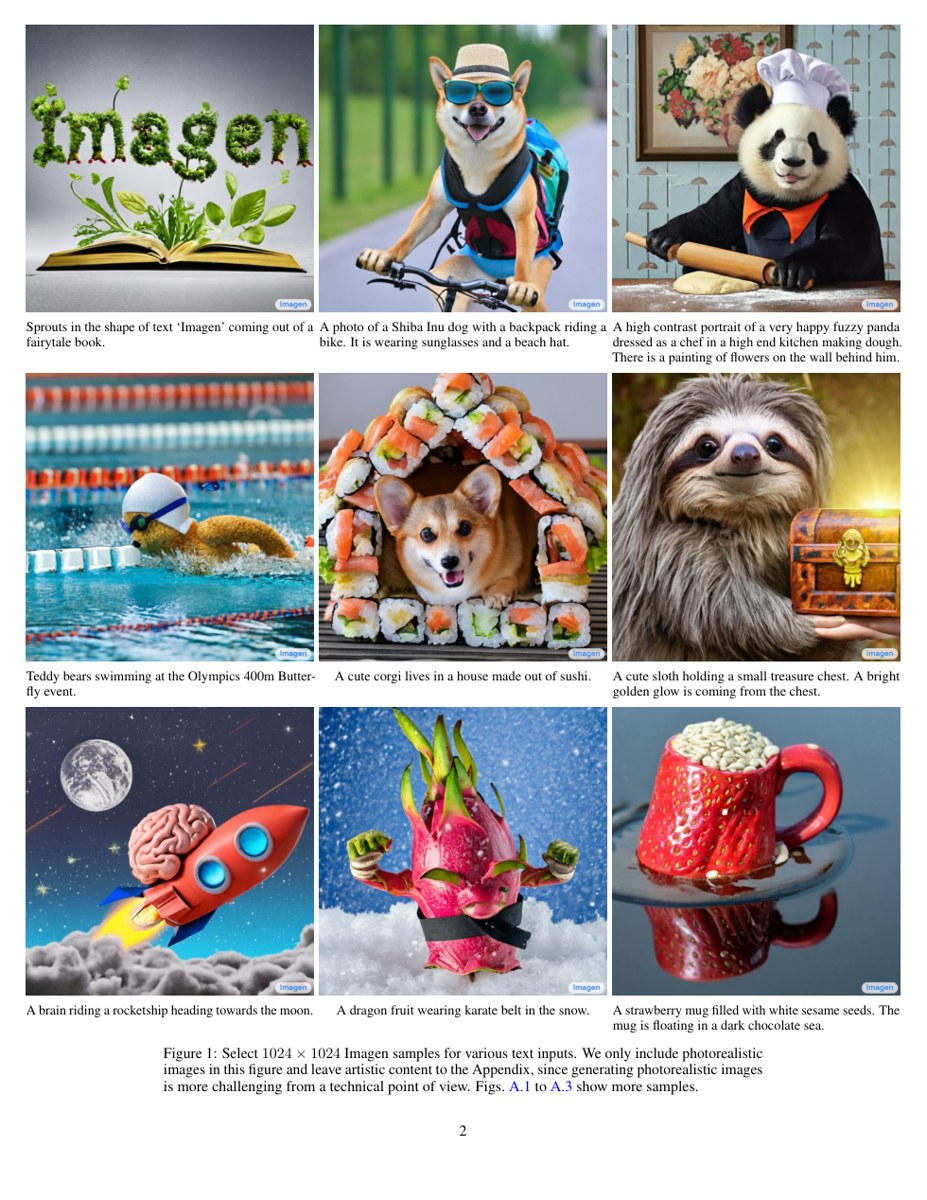
Imagen uses a large text encoder and diffusion decoders. The research highlights gains in image–text alignment from scaling the language model. It develops a direction that later multimodal systems also pursue: improvements in understanding language can change the visual capabilities and controllability of image generation.
 View full image ↗
Page 2 of the linked paper PDF, preserving its original figures and language. The source file identifies the edition; later revision or reprint dates do not replace the node’s historical date.
Chitwan Saharia et al. / Google Research · original paper · Image rights remain with their respective holders; no open licence is asserted
Source · Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding ↗RESEARCH ACCOUNT
The scale of the text encoder becomes an image-generation question.
ANTI-AI ARCHIVE · Revised 2026-10-02
Method and contribution
Imagen combines a large language model’s text representations with diffusion synthesis. The paper compares scaling the text encoder with scaling the image model and introduces DrawBench for challenging prompts. Human preferences and metrics concern those benchmarks; a research demonstration does not establish a generally available commercial service.
Section sources: Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding
Art-historical interpretation
Visual output is also shaped by linguistic categories, relations and descriptions. Studying generated images therefore requires examining how text encoding organises objects, attributes and spatial relations as well as studying image training material.
Section sources: Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding
Sources for this account
Author or conference abstract and version record read; full proofs and experiments were not independently reproduced.
This account expands the archive within the cited scope. Historical interpretation is not presented as the original author’s statement or as a proven causal influence. The account and translation are AI-assisted, pending independent human review. Section references identify evidence without claiming independent verification of every historical statement.
Continue with a comparative question
Compare the methods, forms of control or presentation contexts of this entry and CycleGAN.
Compare the methods, forms of control or presentation contexts of this entry and Imagen 3.
Dates & version record
Date displayed for this node: 2022-05 · Historical date recorded for the source: 2022-05
These dates refer to the historical event or recorded version, not this page’s publication date. The original date precision and unresolved questions are retained.
Original sources & further reading
These links lead to the cited paper, article, institution or conference page. External texts retain their source languages.
Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding
https://arxiv.org/abs/2205.11487
Current cited URL
Imagen
https://imagen.research.google/
URL cited in a research master or supplement; it may have moved or expired
Provenance, translation & verification
Timeline entry #142 · Historical node
Research materials & supplement references · 3
AI Art Genealogy Research Master · p. 25 · 083
Date as recorded: 2022-05
Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding ↗
Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding
GenAI Visual Release Chronology Research Master · p. 5 · R020
Date as recorded: 2022-05
Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding ↗
Google Imagen
GenAI Visual Release Chronology Research Master · p. 6 · R021
Date as recorded: 2022-05
Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding ↗
Imagen
Archive account based on the listed research materials, not a full translation of the linked work. AI-assisted translation; independent human review pending.
The master’s research claims and dates await independent verification.
Cite this node
ANTI-AI ARCHIVE. Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding. Art-history node #142. https://salondesrefuses.cn/en/art-history/083
For specific historical claims, also cite the original sources above and include your access date. This account is not a full translation of the linked work.
Adjacent nodes follow chronological order; adjacency does not establish direct influence or causation.