
Introduction
Imagen 3 is introduced at Google I/O and subsequently enters Gemini and Vertex AI. The master treats this as an example of general-purpose AI platforms incorporating image generation as a standard capability within their model stacks, rather than maintaining it solely as a separate experimental product.
 View full image ↗
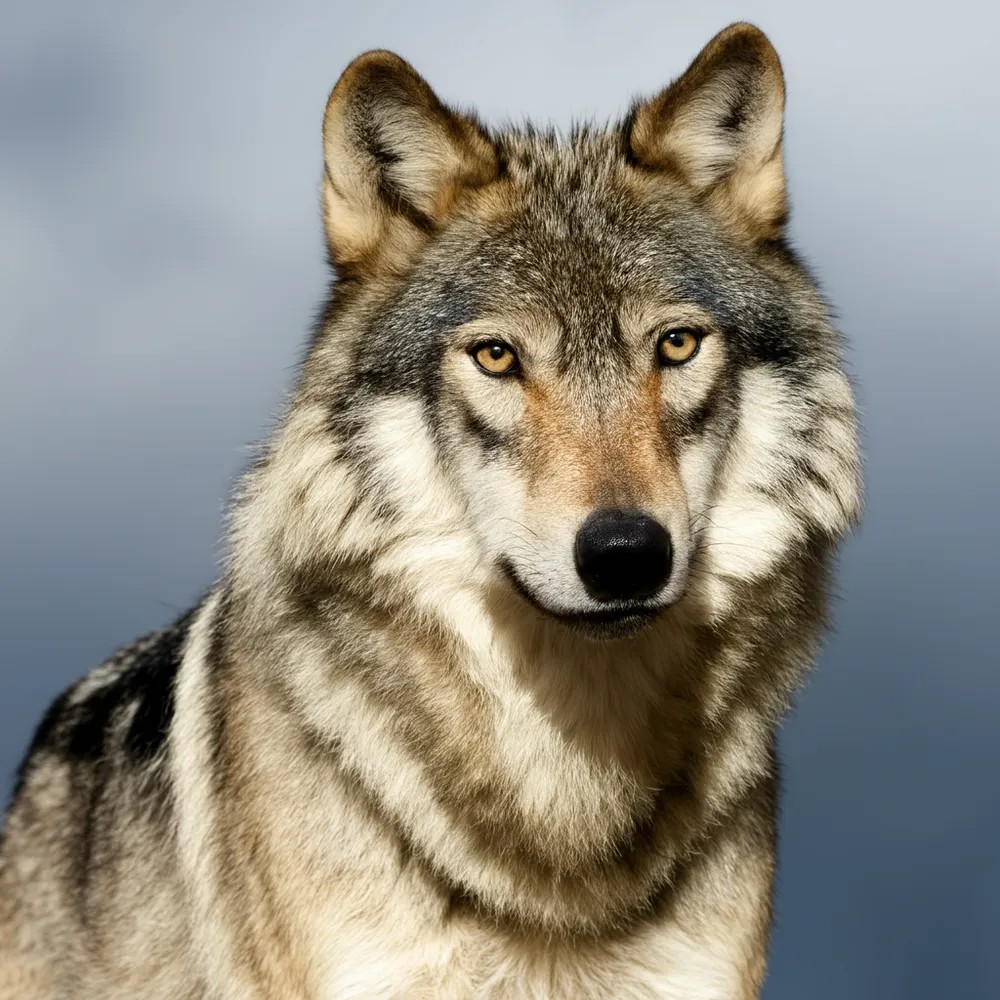
Close-up wolf example from the Google I/O 2024 Imagen 3 announcement. A model-generated image published with the release, not wildlife photography.
Google DeepMind · Rights in the original image and document remain with their respective holders
Source · Veo and Imagen 3 · Google I/O 2024 ↗RESEARCH ACCOUNT
The image-model branch of a broader platform announcement.
ANTI-AI ARCHIVE · Revised 2026-10-02
Release and use
Imagen 3 appears beside Veo in the May 2024 announcement. Google emphasises detail, prompt following and fewer artefacts while inviting access applications. Announcement and later integration into individual products are different events; current documentation cannot automatically establish the original access conditions.
Section sources: Imagen 3
Change in creative practice
Reading it beside Veo reveals how a company assembles media capabilities into creative services. Image-specific changes still require analysis; sharing a platform does not imply identical training or rights arrangements across images, video and sound.
Section sources: Imagen 3
Sources for this account
Official release scope and demonstration descriptions read; vendor performance claims are not treated as independent test results.
This account expands the archive within the cited scope. Historical interpretation is not presented as the original author’s statement or as a proven causal influence. The account and translation are AI-assisted, pending independent human review. Section references identify evidence without claiming independent verification of every historical statement.
Continue with a comparative question
Compare the methods, forms of control or presentation contexts of this entry and Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding.
Compare the methods, forms of control or presentation contexts of this entry and Veo video generation model.
Compare the methods, forms of control or presentation contexts of this entry and Imagen 4.
Dates & version record
Date displayed for this node: 2024-05 / 2024-08 · Historical date recorded for the source: 2024-05 / 2024-08
These dates refer to the historical event or recorded version, not this page’s publication date. The original date precision and unresolved questions are retained.
Original sources & further reading
These links lead to the cited paper, article, institution or conference page. External texts retain their source languages.
Imagen 3
https://blog.google/innovation-and-ai/products/google-generative-ai-veo-imagen-3/
Current cited URL
Provenance, translation & verification
Timeline entry #240 · Historical node
Research materials & supplement references · 3
AI Art Genealogy Research Master · p. 35 · 123
Date as recorded: 2024-05 / 2024-08
Imagen 3 ↗
Imagen 3
GenAI Visual Release Chronology Research Master · p. 21 · R108
Date as recorded: 2024-05
Imagen 3 ↗
Imagen 3 announced
GenAI Visual Release Chronology Research Master · p. 21 · R110
Date as recorded: 2024-05/2024-08
Imagen 3 ↗
Google Imagen 3
Archive account based on the listed research materials, not a full translation of the linked work. AI-assisted translation; independent human review pending.
The master’s research claims and dates await independent verification.
Cite this node
ANTI-AI ARCHIVE. Imagen 3. Art-history node #240. https://salondesrefuses.cn/en/art-history/123
For specific historical claims, also cite the original sources above and include your access date. This account is not a full translation of the linked work.
Adjacent nodes follow chronological order; adjacency does not establish direct influence or causation.