
Introduction
Stable Video Diffusion makes latent video diffusion available to researchers and developers, extending an open generative ecosystem from still images toward video. It also points toward increasingly shared infrastructure between image and video models, including software for arranging and adapting generation processes.
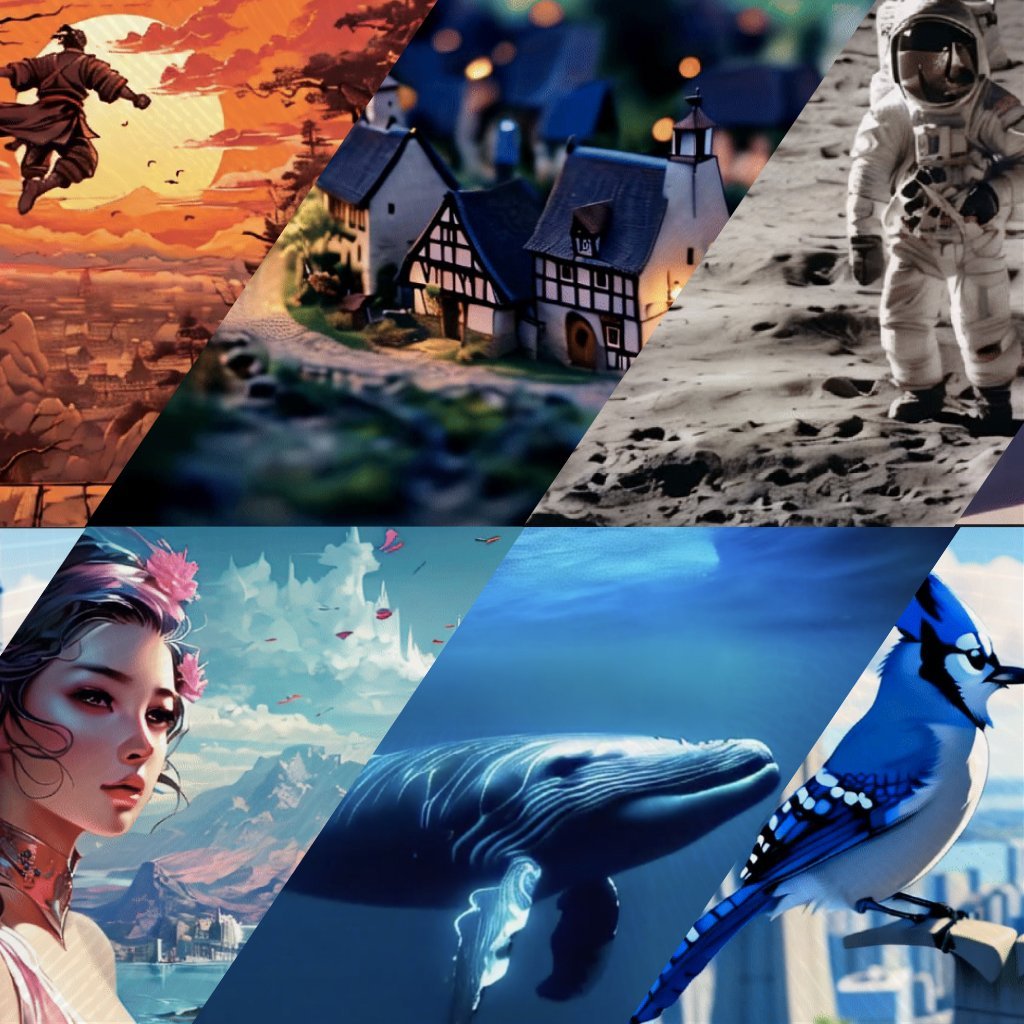 View full image ↗
Stable Video Diffusion: illustration from the cited release page. Lettering retains its original language. This is a source illustration, not a sample generated by this archive.
Stability AI / research collaborators · source publication · Image rights remain with their respective holders; no open licence is asserted
Source · Stable Video Diffusion ↗RESEARCH ACCOUNT
Image-to-video models released as a research preview.
ANTI-AI ARCHIVE · Revised 2026-10-03
What the release contained
The November 2023 announcement releases Stable Video Diffusion code and weights and distinguishes image-to-video models generating 14 and 25 frames. A waiting list for a future text-to-video web experience is separate from the research release. The presence of that list does not establish a generally available text-to-video service at that date.
Section sources: Stable Video Diffusion
From image to movement
A still image becomes the starting condition for a short movement, establishing a different form of control from frame-by-frame animation. Historical records should separate research weights, web services and later fine-tuned applications. Download availability does not itself establish permission for every commercial use.
Section sources: Stable Video Diffusion
Research paper and release dates
First submitted on 25 November 2023, the paper distinguishes image pretraining, video pretraining and high-quality video fine-tuning, including captioning and filtering. Its research configurations should not all be attributed to one initially released checkpoint; the existing release chronology is retained.
Section sources: Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets
Sources for this account
Official 21 November 2023 announcement read for models, code, weights and research-preview scope.
Read the abstract, authors and arXiv submission record, not a full-paper review.
This account expands the archive within the cited scope. Historical interpretation is not presented as the original author’s statement or as a proven causal influence. The account and translation are AI-assisted, pending independent human review. Section references identify evidence without claiming independent verification of every historical statement.
Continue with a comparative question
Compare the methods, forms of control or presentation contexts of this entry and Latent Diffusion Models.
Compare the methods, forms of control or presentation contexts of this entry and Gen-2 multimodal video generation.
Dates & version record
Date displayed for this node: 2023-11 · Historical date recorded for the source: 2023-11
These dates refer to the historical event or recorded version, not this page’s publication date. The original date precision and unresolved questions are retained.
Original sources & further reading
These links lead to the cited paper, article, institution or conference page. External texts retain their source languages.
Stable Video Diffusion
https://stability.ai/news/stable-video-diffusion-open-ai-video-model
Current cited URL
Stable Video Diffusion
https://stability.ai/news-updates/stable-video-diffusion-open-ai-video-model
URL cited in a research master or supplement; it may have moved or expired
Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets
https://arxiv.org/abs/2311.15127
URL cited in a research master or supplement; it may have moved or expired
Provenance, translation & verification
Timeline entry #217 · Historical node
Research materials & supplement references · 4
AI Art Genealogy Research Master · p. 32 · 109
Date as recorded: 2023-11
Stable Video Diffusion ↗
Stable Video Diffusion
GenAI Visual Release Chronology Research Master · p. 17 · R084
Date as recorded: 2023-11-21
Stable Video Diffusion ↗
Stable Video Diffusion
GenAI Visual Release Chronology Research Master · p. 17 · R087
Date as recorded: 2023-11
Stable Video Diffusion ↗
Stable Video Diffusion
Recent research papers: additions and reconciled sources since 2022 · Read the abstract, authors and arXiv submission record, not a full-paper review. · 037
Date as recorded: 2023-11-25
Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets ↗
Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets
Archive account based on the listed research materials, not a full translation of the linked work. AI-assisted translation; independent human review pending.
The master’s research claims and dates await independent verification.
Cite this node
ANTI-AI ARCHIVE. Stable Video Diffusion. Art-history node #217. https://salondesrefuses.cn/en/art-history/109
For specific historical claims, also cite the original sources above and include your access date. This account is not a full translation of the linked work.
Adjacent nodes follow chronological order; adjacency does not establish direct influence or causation.