
Introduction
PixArt-α focuses on diffusion Transformers, pretrained text encoders and efficient training. It is an open research node leading into the wider development of Transformer- and flow-based image systems in 2024. Its significance concerns both architectural choices and the resources needed to train visual models.
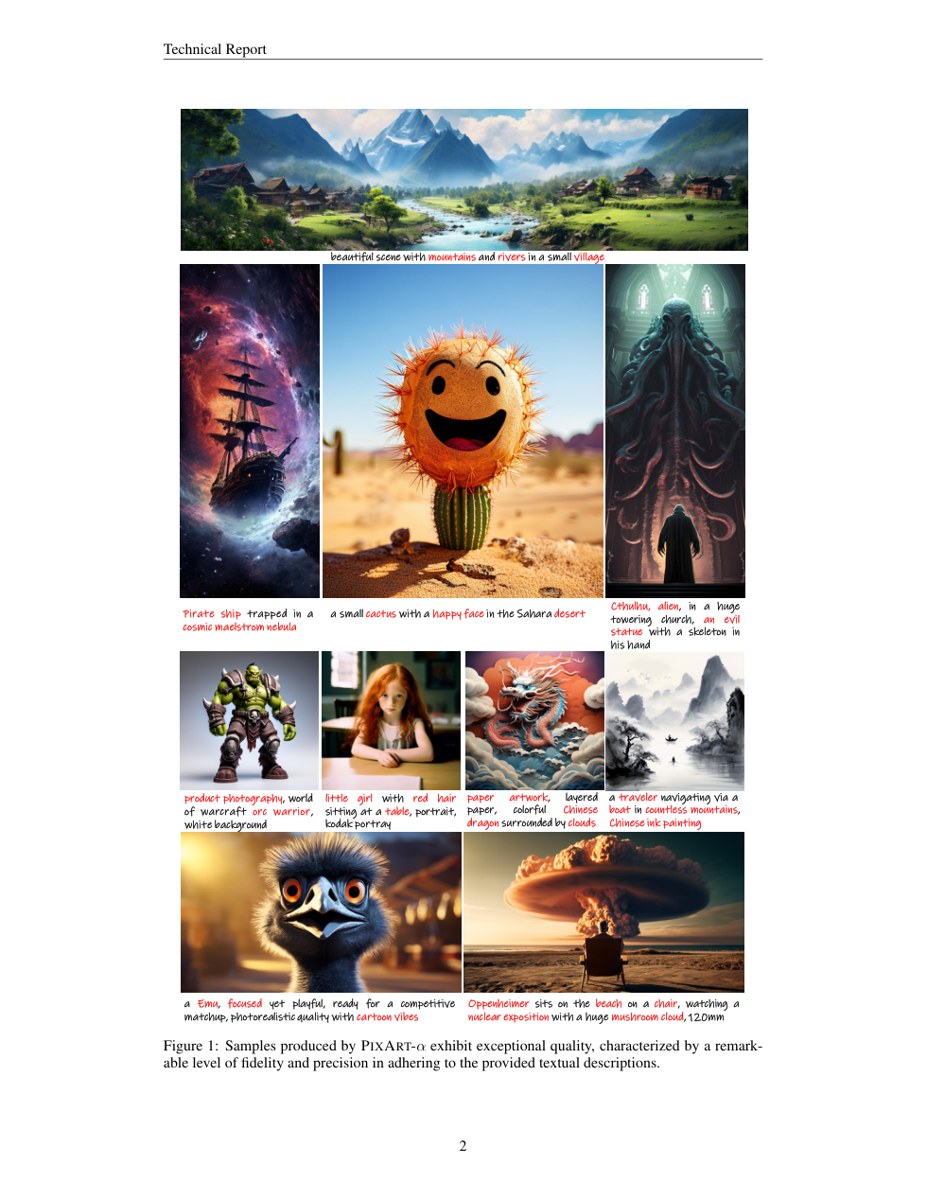 View full image ↗
Page 2 of the linked paper PDF, preserving its original figures and language. The source file identifies the edition; later revision or reprint dates do not replace the node’s historical date.
Junsong Chen et al. · original paper · Image rights remain with their respective holders; no open licence is asserted
Source · PixArt-α: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis ↗RESEARCH ACCOUNT
Connecting training cost, caption density and image quality.
ANTI-AI ARCHIVE · Revised 2026-10-02
Method and contribution
PixArt-α separates training for pixel dependencies, text–image alignment and aesthetic quality, introducing text conditioning into a diffusion transformer. It emphasises information-rich captions, supplemented through a vision–language model. Its cost comparisons concern particular training configurations and cannot establish the environmental burden of all image models.
Section sources: PixArt-α: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis
Art-historical interpretation
The node shows that visual models depend on how images are described as well as how many are collected. Automated captioning imports another model’s classifications and linguistic choices into training. “Data quality” consequently includes cultural judgements that require analysis.
Section sources: PixArt-α: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis
Sources for this account
Author or conference abstract and version record read; full proofs and experiments were not independently reproduced.
This account expands the archive within the cited scope. Historical interpretation is not presented as the original author’s statement or as a proven causal influence. The account and translation are AI-assisted, pending independent human review. Section references identify evidence without claiming independent verification of every historical statement.
Continue with a comparative question
Compare the methods, forms of control or presentation contexts of this entry and CycleGAN.
Compare the methods, forms of control or presentation contexts of this entry and LAION-5B: An open large-scale dataset for training next generation image-text models.
Dates & version record
Date displayed for this node: 2023-09 · Historical date recorded for the source: 2023-09
These dates refer to the historical event or recorded version, not this page’s publication date. The original date precision and unresolved questions are retained.
Original sources & further reading
These links lead to the cited paper, article, institution or conference page. External texts retain their source languages.
PixArt-α: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis
https://arxiv.org/abs/2310.00426
Current cited URL
Provenance, translation & verification
Timeline entry #208 · Historical node
Research materials & supplement references · 2
AI Art Genealogy Research Master · p. 34 · 118
Date as recorded: 2023-09
PixArt-α: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis ↗
PixArt-α: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis
GenAI Visual Release Chronology Research Master · p. 15 · R076
Date as recorded: 2023-09
PixArt-α: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis ↗
Chen et al. — PixArt-α
Archive account based on the listed research materials, not a full translation of the linked work. AI-assisted translation; independent human review pending.
The master’s research claims and dates await independent verification.
Cite this node
ANTI-AI ARCHIVE. PixArt-α: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis. Art-history node #208. https://salondesrefuses.cn/en/art-history/118
For specific historical claims, also cite the original sources above and include your access date. This account is not a full translation of the linked work.
Adjacent nodes follow chronological order; adjacency does not establish direct influence or causation.