
Introduction
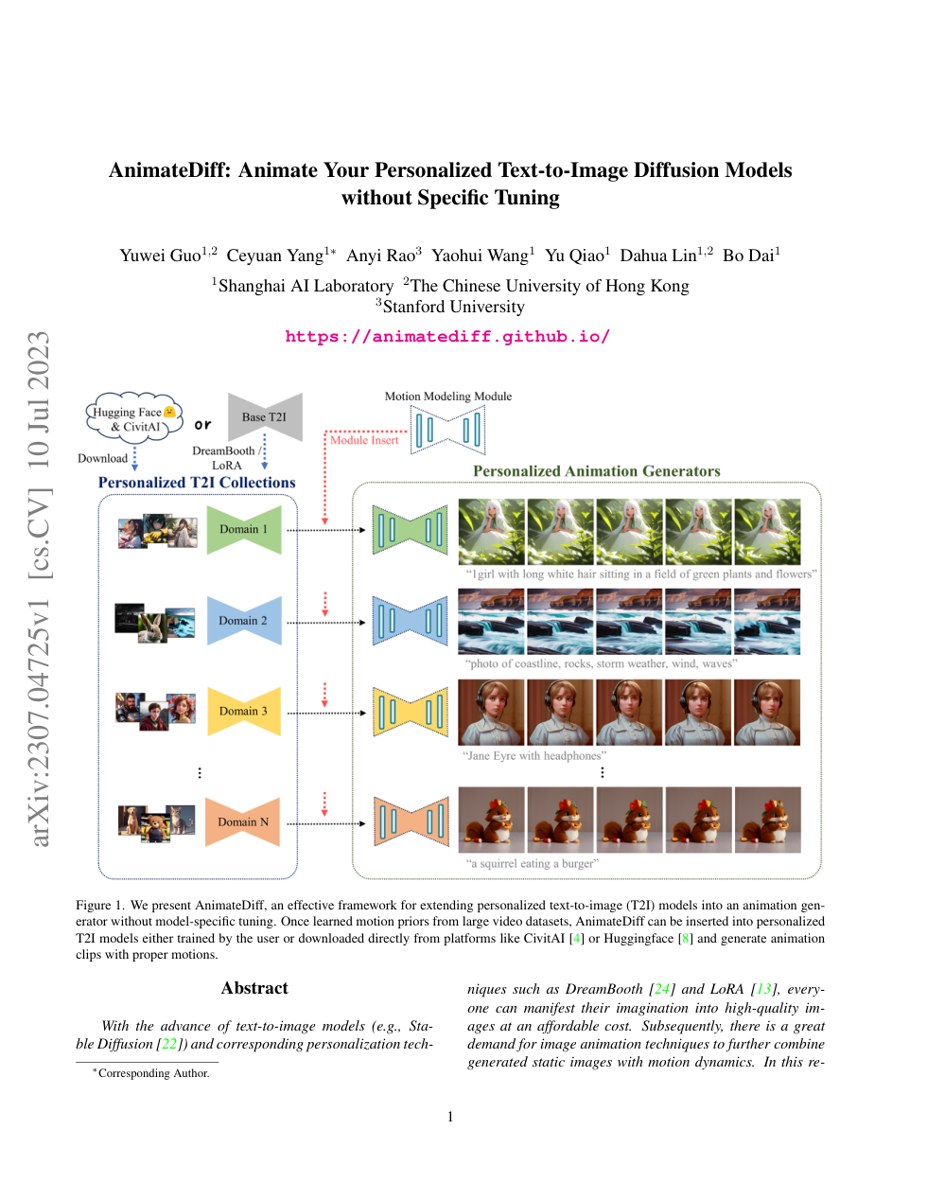
AnimateDiff introduces motion modelling as a pluggable component within personalized text-to-image diffusion systems. Existing character models, styles and community assets can participate in animated outputs. This extends generation from still images toward video while retaining parts of the earlier image-model ecosystem.
 View full image ↗
Page 1 of the linked paper PDF, preserving its original figures and language. The source file identifies the edition; later revision or reprint dates do not replace the node’s historical date.
Yuwei Guo et al. · original paper · Image rights remain with their respective holders; no open licence is asserted
Source · AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning ↗RESEARCH ACCOUNT
Adding a reusable motion module to personalised image models.
ANTI-AI ARCHIVE · Revised 2026-10-02
Method and contribution
AnimateDiff learns transferable motion priors so personalised text-to-image models sharing a base can generate animation without training a complete video system for each one. MotionLoRA adapts the motion module to new patterns with comparatively limited data. Appearance and movement are thus handled by distinguishable components.
Section sources: AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning
Art-historical interpretation
Modularity connects existing model communities to animation production. An account of a work should record base weights, personalisation and the motion module together. Naming only one product obscures multiple contributors and the sources of movement.
Section sources: AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning
Sources for this account
Author or conference abstract and version record read; full proofs and experiments were not independently reproduced.
This account expands the archive within the cited scope. Historical interpretation is not presented as the original author’s statement or as a proven causal influence. The account and translation are AI-assisted, pending independent human review. Section references identify evidence without claiming independent verification of every historical statement.
Continue with a comparative question
Compare the methods, forms of control or presentation contexts of this entry and LoRA: Low-Rank Adaptation of Large Language Models + diffusion community adoption.
Compare the methods, forms of control or presentation contexts of this entry and DreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation.
Dates & version record
Date displayed for this node: 2023 · Historical date recorded for the source: 2023
These dates refer to the historical event or recorded version, not this page’s publication date. The original date precision and unresolved questions are retained.
Original sources & further reading
These links lead to the cited paper, article, institution or conference page. External texts retain their source languages.
AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning
https://arxiv.org/abs/2307.04725
Current cited URL
Provenance, translation & verification
Timeline entry #176 · Historical node
Research materials & supplement references · 2
AI Art Genealogy Research Master · p. 31 · 106
Date as recorded: 2023
AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning ↗
AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning
GenAI Visual Release Chronology Research Master · p. 18 · R091
Date as recorded: 2023
AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning ↗
AnimateDiff
Archive account based on the listed research materials, not a full translation of the linked work. AI-assisted translation; independent human review pending.
The master’s research claims and dates await independent verification.
Cite this node
ANTI-AI ARCHIVE. AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning. Art-history node #176. https://salondesrefuses.cn/en/art-history/106
For specific historical claims, also cite the original sources above and include your access date. This account is not a full translation of the linked work.
Adjacent nodes follow chronological order; adjacency does not establish direct influence or causation.