
Introduction
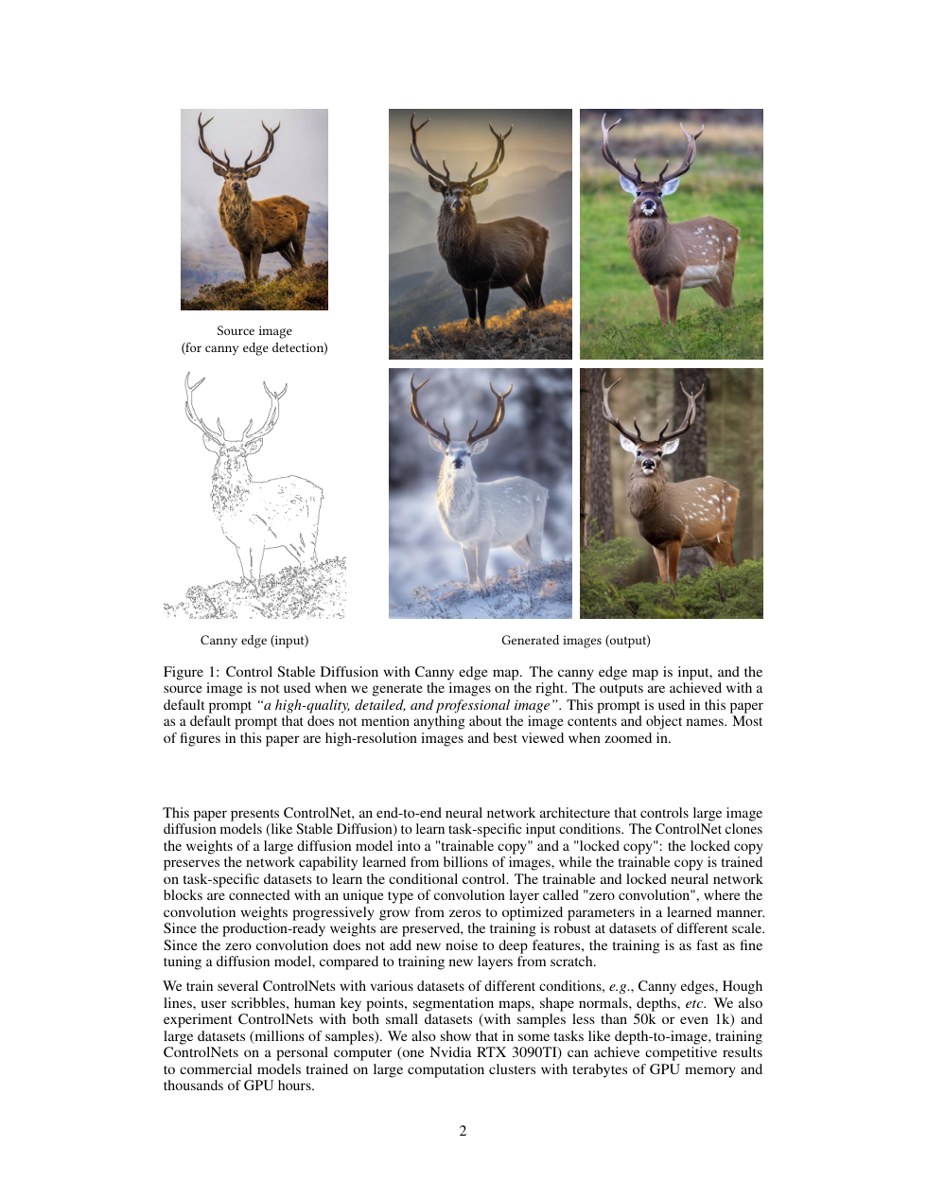
ControlNet freezes a pretrained diffusion backbone and learns spatial conditions through an additional network. It extends control from textual semantics toward geometry and composition. This is one technical condition for more specialized production workflows, in which artists or designers need to specify structure as well as subject matter.
 View full image ↗
Page 2 of the linked paper PDF, preserving its original figures and language. The source file identifies the edition; later revision or reprint dates do not replace the node’s historical date.
Lvmin Zhang; Anyi Rao; Maneesh Agrawala · original paper · Image rights remain with their respective holders; no open licence is asserted
Source · Adding Conditional Control to Text-to-Image Diffusion Models ↗RESEARCH ACCOUNT
Making edges, depth and pose explicit generation conditions.
ANTI-AI ARCHIVE · Revised 2026-10-02
Method and contribution
ControlNet locks a pretrained diffusion model and adds trainable conditioning branches connected through zero-initialised convolutions. Experiments cover edges, depth, segmentation and human pose, separately and in combination, with different training-set sizes. It adds control interfaces rather than replacing the underlying generator.
Section sources: Adding Conditional Control to Text-to-Image Diffusion Models
Art-historical interpretation
Composition, movement and surface detail can be organised in layers. This helps explain potential illustration and animation workflows without treating a technical demonstration as proof of industry adoption. Individual works still require records of control-image preparation, model versions and subsequent editing.
Section sources: Adding Conditional Control to Text-to-Image Diffusion Models
Sources for this account
Author or conference abstract and version record read; full proofs and experiments were not independently reproduced.
This account expands the archive within the cited scope. Historical interpretation is not presented as the original author’s statement or as a proven causal influence. The account and translation are AI-assisted, pending independent human review. Section references identify evidence without claiming independent verification of every historical statement.
Continue with a comparative question
Compare the methods, forms of control or presentation contexts of this entry and SPADE paper / GauGAN demo.
Compare the methods, forms of control or presentation contexts of this entry and T2I-Adapter: Learning Adapters to Dig out More Controllable Ability for Text-to-Image Diffusion Models.
Dates & version record
Date displayed for this node: 2023-02 · Historical date recorded for the source: 2023-02
These dates refer to the historical event or recorded version, not this page’s publication date. The original date precision and unresolved questions are retained.
Original sources & further reading
These links lead to the cited paper, article, institution or conference page. External texts retain their source languages.
Adding Conditional Control to Text-to-Image Diffusion Models
https://arxiv.org/abs/2302.05543
Current cited URL
Provenance, translation & verification
Timeline entry #181 · Historical node
Research materials & supplement references · 2
AI Art Genealogy Research Master · p. 29 · 097
Date as recorded: 2023-02
Adding Conditional Control to Text-to-Image Diffusion Models ↗
Adding Conditional Control to Text-to-Image Diffusion Models
GenAI Visual Release Chronology Research Master · p. 12 · R053
Date as recorded: 2023-02
Adding Conditional Control to Text-to-Image Diffusion Models ↗
ControlNet
Archive account based on the listed research materials, not a full translation of the linked work. AI-assisted translation; independent human review pending.
The master’s research claims and dates await independent verification.
Cite this node
ANTI-AI ARCHIVE. Adding Conditional Control to Text-to-Image Diffusion Models. Art-history node #181. https://salondesrefuses.cn/en/art-history/097
For specific historical claims, also cite the original sources above and include your access date. This account is not a full translation of the linked work.
Adjacent nodes follow chronological order; adjacency does not establish direct influence or causation.