
Introduction
Natural-language supervision creates a shared image-text representation that soon becomes a control signal for community art workflows. This dates the initial announcement; the later paper is a separate node.
 View full image ↗
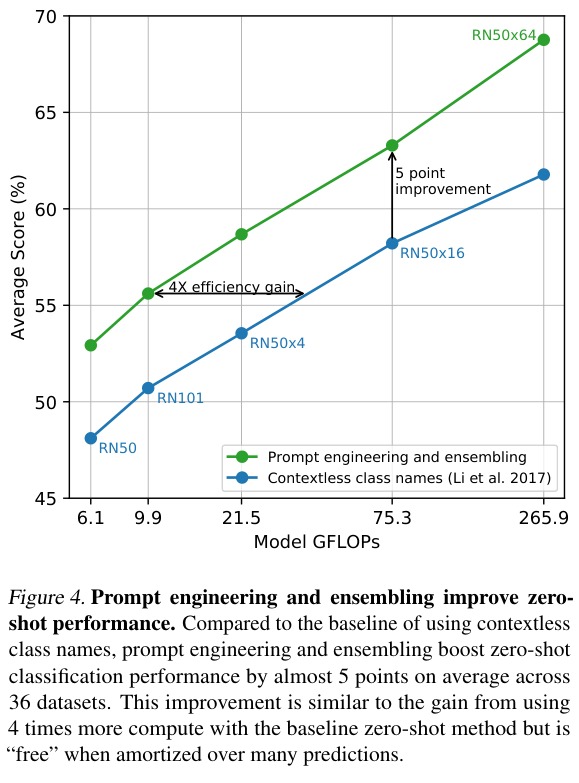
Figure 4 from the CLIP paper, comparing prompt engineering and ensembling. The March 2021 paper followed the January announcement; the plotted results are those reported by its authors.
Alec Radford et al. / OpenAI · Rights in the original image and document remain with their respective holders
Source · Learning Transferable Visual Models From Natural Language Supervision ↗RESEARCH ACCOUNT
A research announcement connects visual recognition with natural language.
ANTI-AI ARCHIVE · Revised 2026-10-02
Release and use
The CLIP announcement uses internet image–text supervision to learn transferable visual representations and demonstrates zero-shot classification, addressing limitations of fixed-category datasets. This node preserves public presentation; the paper and community generation workflows are recorded separately, avoiding confusion between a recognition model and a stand-alone image generator.
Section sources: CLIP announced
Change in creative practice
Public explanation and code make a matching method available for others’ tool combinations. Its cultural role must be traced through actual connections, such as guiding images with similarity scores, rather than deriving every later artistic influence directly from the announcement.
Section sources: CLIP announced
Sources for this account
Official release scope and demonstration descriptions read; vendor performance claims are not treated as independent test results.
This account expands the archive within the cited scope. Historical interpretation is not presented as the original author’s statement or as a proven causal influence. The account and translation are AI-assisted, pending independent human review. Section references identify evidence without claiming independent verification of every historical statement.
Continue with a comparative question
Compare the methods, forms of control or presentation contexts of this entry and Learning Transferable Visual Models From Natural Language Supervision.
Compare the methods, forms of control or presentation contexts of this entry and VQGAN+CLIP community workflow.
Dates & version record
Date displayed for this node: 2021-01 · Historical date recorded for the source: 2021-01
Month or year precision follows the master; an exact release date awaits independent verification.
These dates refer to the historical event or recorded version, not this page’s publication date. The original date precision and unresolved questions are retained.
Original sources & further reading
These links lead to the cited paper, article, institution or conference page. External texts retain their source languages.
This is the archive’s bilingual research abstract. The external link is an original source, not a claim that the publisher offers full text in both languages.
Provenance, translation & verification
Timeline entry #118 · Model
Research materials & supplement references · 1
GenAI Visual Release Chronology Research Master · p. 2 · R001
Date as recorded: 2021-01
CLIP announced ↗
CLIP announced
Archive account based on the listed research materials, not a full translation of the linked work. AI-assisted translation; independent human review pending.
The master’s research claims and dates await independent verification.
Cite this node
ANTI-AI ARCHIVE. CLIP announced. Art-history node #118. https://salondesrefuses.cn/en/art-history/141
For specific historical claims, also cite the original sources above and include your access date. This account is not a full translation of the linked work.
Adjacent nodes follow chronological order; adjacency does not establish direct influence or causation.