
Introduction
DALL·E 2 combines CLIP representations with a diffusion-based image prior and decoder, improving realism and correspondence with text. Its research preview, beta and later access without a waitlist expand during 2022. The master emphasises this product transition as a step in the international popularization of text-to-image generation.
 View full image ↗
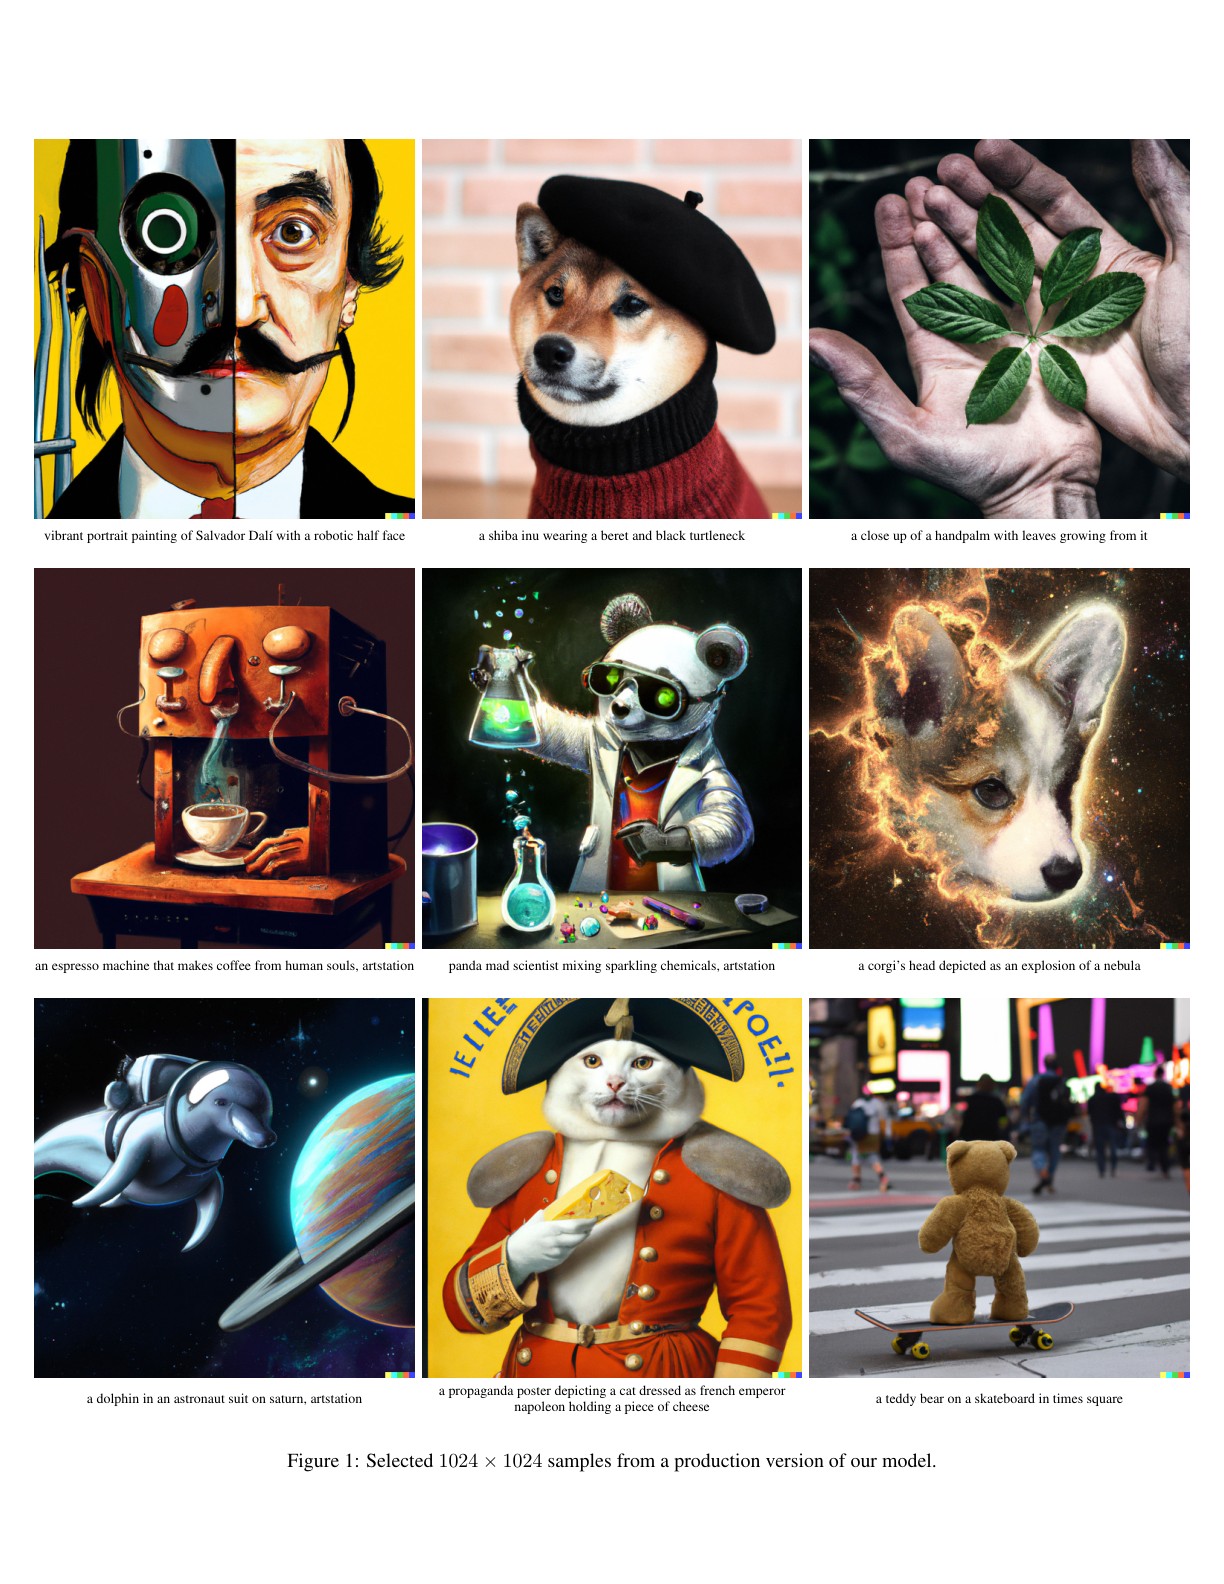
Model-output examples on page 2 of the original DALL·E 2 paper, retaining the images and prompt layout. A 2022 research plate.
Aditya Ramesh et al. / OpenAI · Rights remain with the respective holders; reproduction does not imply an open licence
Source · Hierarchical Text-Conditional Image Generation with CLIP Latents · Figure 1 ↗RESEARCH ACCOUNT
From a research demonstration to a tool for generation and editing.
ANTI-AI ARCHIVE · Revised 2026-10-03
Release and use
DALL·E 2 connects text conditioning and image representations with diffusion generation. Official demonstrations include editing existing pictures and producing variations as well as generating from descriptions. Research preview, beta access and removal of the waitlist in 2022 are different stages of availability.
Section sources: Hierarchical Text-Conditional Image Generation with CLIP Latents / DALL·E 2 product
Change in creative practice
Generation becomes an iterative making process, using language, existing images and local editing requests. Preserving intermediate states helps distinguish a user’s composition from the model’s additions. A polished final output alone cannot explain how control was distributed during production.
Section sources: Hierarchical Text-Conditional Image Generation with CLIP Latents / DALL·E 2 product
Research paper and release dates
First submitted on 13 April 2022, the paper predicts a CLIP image embedding from text and then decodes an image conditioned on it, comparing prior implementations. This node retains its existing combined product/research chronology; the preprint date is recorded separately.
Section sources: Hierarchical Text-Conditional Image Generation with CLIP Latents
Sources for this account
Official release scope and demonstration descriptions read; vendor performance claims are not treated as independent test results.
Read the abstract, authors and arXiv submission record, not a full-paper review.
This account expands the archive within the cited scope. Historical interpretation is not presented as the original author’s statement or as a proven causal influence. The account and translation are AI-assisted, pending independent human review. Section references identify evidence without claiming independent verification of every historical statement.
Continue with a comparative question
Compare the methods, forms of control or presentation contexts of this entry and Latent Diffusion Models.
Compare the methods, forms of control or presentation contexts of this entry and DALL·E 3 announced.
Dates & version record
Date displayed for this node: 2022 · Historical date recorded for the source: 2022-03
The master gives 2022-03. Product and paper release months require reconciliation; this view uses year precision.
These dates refer to the historical event or recorded version, not this page’s publication date. The original date precision and unresolved questions are retained.
Original sources & further reading
These links lead to the cited paper, article, institution or conference page. External texts retain their source languages.
Hierarchical Text-Conditional Image Generation with CLIP Latents / DALL·E 2 product
https://openai.com/index/dall-e-2/
Current cited URL
Hierarchical Text-Conditional Image Generation with CLIP Latents
https://arxiv.org/abs/2204.06125
URL cited in a research master or supplement; it may have moved or expired
Provenance, translation & verification
Timeline entry #134 · Historical node
Research materials & supplement references · 4
AI Art Genealogy Research Master · p. 25 · 082
Date as recorded: 2022-03
Hierarchical Text-Conditional Image Generation with CLIP Latents / DALL·E 2 product ↗
Hierarchical Text-Conditional Image Generation with CLIP Latents / DALL·E 2 product
GenAI Visual Release Chronology Research Master · p. 5 · R016
Date as recorded: 2022-03
Hierarchical Text-Conditional Image Generation with CLIP Latents / DALL·E 2 product ↗
DALL·E 2
GenAI Visual Release Chronology Research Master · p. 5 · R017
Date as recorded: 2022-03
Hierarchical Text-Conditional Image Generation with CLIP Latents / DALL·E 2 product ↗
DALL·E 2 research preview / paper
Recent research papers: additions and reconciled sources since 2022 · Read the abstract, authors and arXiv submission record, not a full-paper review. · 034
Date as recorded: 2022-04-13
Hierarchical Text-Conditional Image Generation with CLIP Latents ↗
Hierarchical Text-Conditional Image Generation with CLIP Latents
Archive account based on the listed research materials, not a full translation of the linked work. AI-assisted translation; independent human review pending.
The master’s research claims and dates await independent verification.
Cite this node
ANTI-AI ARCHIVE. Hierarchical Text-Conditional Image Generation with CLIP Latents / DALL·E 2 product. Art-history node #134. https://salondesrefuses.cn/en/art-history/082
For specific historical claims, also cite the original sources above and include your access date. This account is not a full translation of the linked work.
Adjacent nodes follow chronological order; adjacency does not establish direct influence or causation.